№ 122026.11.15Essay8 minAlso in Portuguese
An enterprise LLM lab in my living room
A single gateway, a capped key per project, capability aliases, cross-provider fallback and a router that picks the model from the question. I built all of it on my home computer to fail cheaply before proposing it at work, and the agent on this site runs on top of it.
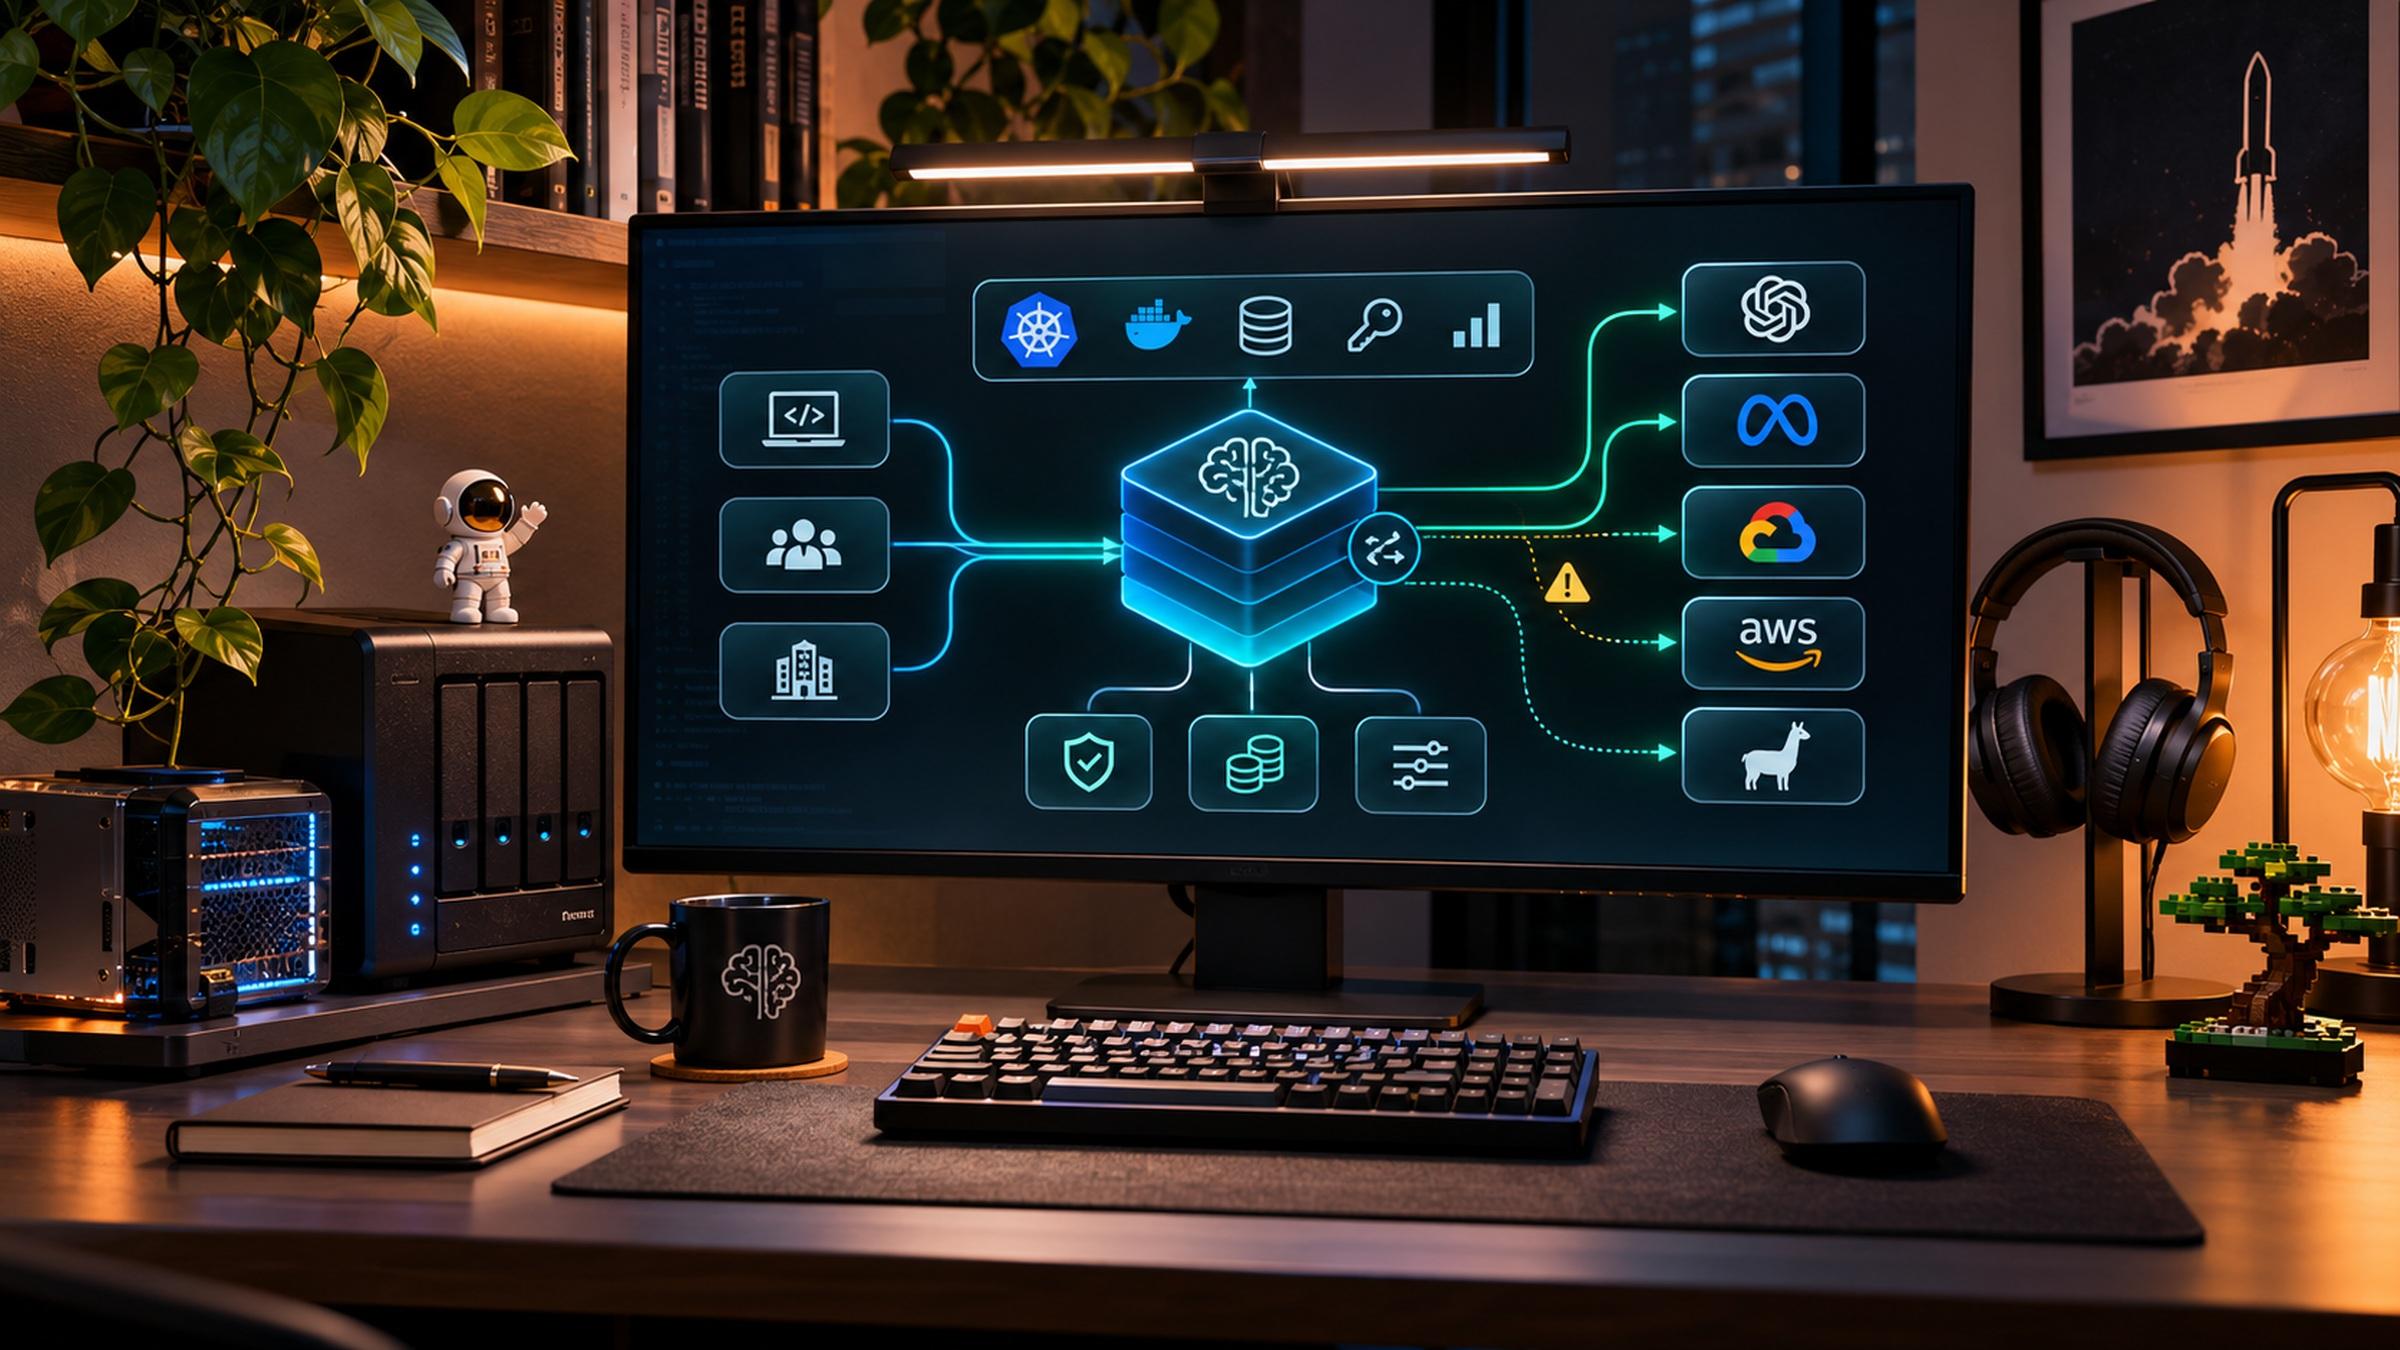
Whoever designs LLM architecture at a company almost never has a place to fail cheaply. The gateway is already in production, every key has an owner, every new model goes through procurement, and testing what happens when a provider goes down means breaking something somebody is using.
So I built the same architecture at home. A computer with WSL2, a pocket-sized Kubernetes and the usual pay-as-you-go API keys. There I break things on purpose, measure the effect, and only then bring the idea to the table.
This post covers the pieces, how I validate each one, and how the "Ask about me" agent on this site's home page runs on top of them. The full path of an agent question is on the How it works page.
The pieces
The design is the same one I argue for at work: apps do not talk to any provider, they talk to a gateway.
- Kubernetes: a k3d cluster (k3s inside Docker) on WSL2. Each thing gets its own namespace; the gateway lives in
llm. - Gateway: LiteLLM with Postgres, compatible with the OpenAI API. Any app inside the cluster points its SDK at
http://litellm.llm.svc.cluster.local:4000and is done. - Publishing: a Cloudflare Tunnel connector running inside the cluster. It opens the tunnel from the inside out, so there is no open port on my router.
Capability aliases, not model names
Projects do not ask for a model by name. They ask for a capability:
| Alias | Points to today | Use |
|---|---|---|
smart |
Claude Opus | heavy reasoning |
fast |
Claude Haiku | quick, cheap answers |
cheap |
Gemini Flash | volume |
embed |
OpenAI embeddings (1536 dimensions) | semantic search |
auto |
Jev decides (see below) | when you do not want to choose |
Swapping the model behind an alias is one line of gateway config. No app changes. For anyone who needs a specific model, there is per-provider passthrough (anthropic/*, openai/*, gemini/*), which resolves 308 models.
Cross-provider fallback
Every alias has a plan B, and the plan B is deliberately on another provider: smart falls back to fast, fast to cheap, cheap back to fast. If Anthropic goes down, fast gets served by Gemini.
I did not take that on the config's word. I broke the Anthropic key on purpose and called smart: Gemini Flash answered.
One key per project, with a cap
Each project gets its own virtual key, with the aliases it may use, a budget and a window:
curl -s http://litellm.localhost/key/generate \
  -H "Authorization: Bearer $LITELLM_MASTER_KEY" -H 'Content-Type: application/json' \
  -d '{"key_alias":"my-project","models":["fast","cheap"],"max_budget":5,"budget_duration":"30d"}'
When the cap is hit, the gateway answers 429 with type: budget_exceeded and refuses the call. It is not a mere alert. An accidental loop burns that project's cap and stops; the whole account stays up. I found that 429 detail by testing, because the documentation does not say it.
Jev: the alias that picks the model
auto is not a model. It is a LiteLLM hook that, before routing, asks Jev, from TypeSafe, whether the prompt calls for fast, smart or cheap, and rewrites the model field with the answer. After that everything is native: fallback, budget and spend are counted against the chosen alias.
The rules I put around it:
- If Jev errors, takes longer than 2 seconds, or answers with confidence below 0.5, the request goes to
fast. The router is never the reason a call fails. - The cost is 200 to 300 extra milliseconds per call on
auto. The other aliases never go through Jev. - To know who answered, the response carries the
X-Litellm-Model-Groupheader, and the spend log gets the tagsauto:<alias>andauto-why:<reason>.
One gotcha only showed up in testing. LiteLLM checks the key's permissions before the hook runs, and at that point it only sees auto. Without care, a key with auto could end up on Opus even without permission for smart. The fix was to make the hook choose only among the destinations the key is already allowed to use: a key with ["auto", "fast", "cheap"] never reaches Opus, and a key with only auto gets a 403.
And there is a point that applies to any third-party router: every prompt on auto also goes to TypeSafe to be classified. For a lab that is acceptable. For this site's public agent it is not, which is why the site key does not have auto.
Playground and validation
I keep the two apart.
Playground is for exploring: the LiteLLM admin UI, to create a key and fire a call by hand, and curl for anything I want to repeat. That is where I learn how a model behaves before it becomes an alias.
Validation is proving by effect, not by config line. A wrong config value is usually accepted silently, so every rule gets a test that only passes if the rule actually holds:
- Permission matrix: for each key, I call each alias and check the status code. The site key, for example:
fast200,smart403,cheap403. - Provider down: I break one provider's key and watch the fallback answer from the other.
- Cap: I give a test key a tiny budget and confirm the 429.
- Router down: with Jev unreachable,
autohas to land onfast.
And testing is where the gotchas no documentation told me about showed up:
- Low
max_tokenswith a reasoning model returns an empty answer. Opus and Gemini Flash spend the whole limit thinking and come back withcontent: null. Haiku, which does not reason, answers normally with the same limit. It is not a routing bug. - The response
modelfield echoes the alias, not the concrete model. To know who answered, look at the fingerprints:vertex_ai_*fields mean Gemini, an extended-thinking signature means Anthropic. /key/infolies about spend. It returnedspend: 0.0for a key whose budget was blown. To read spend, I use/key/listwith the full object.- Deleting the gateway pod looks like a wrong URL. With one replica and a 120-second readiness delay, the Service has no endpoints and Traefik answers 404, not 503, for about 2 minutes.
rollout restartdoes not have that gap, because the old pod serves until the new one is ready.
The real case: this site's agent
The "Ask about me" field on the home page is the lab's first public consumer. Vercel calls llm.kauecode.com, which sits behind Cloudflare Access: without the service token, the edge answers 403 and nothing reaches my home. On the gateway side, the site uses a key of its own, locked to the fast alias, with US$ 5 every 30 days.
When the computer turns off, the agent shows as offline within a minute and comes back by itself. I chose not to fall back to a paid API: if the home platform is down, the agent is down.
The first version already taught me things. The third question of any conversation failed, because each question carries about 9 thousand tokens of context and the key had a 20 thousand tokens-per-minute limit. And the model made up a hobby of mine, which a first-person agent cannot do. The details, the decisions and the code for each step are on the How it works page.
From the living room to the company
None of this is a toy. Every piece has a direct counterpart in a corporate environment, and that is what makes the lab useful:
| At my home | At the company |
|---|---|
| k3d on WSL2 | EKS, AKS or GKE |
| LiteLLM with Postgres | the corporate LLM gateway |
| capped virtual key per project | key per team or product, with budget and owner |
| capability aliases | catalog of approved models |
| cross-provider fallback | continuity when a vendor goes down |
Jev on the auto alias |
routing by cost and complexity |
| Cloudflare Access with a service token | zero trust between services |
| tagged spend log | AI FinOps: who spent, on what, why |
The value is not in copying the stack. It is in walking into the meeting already knowing where it breaks: that the budget 429 is a refusal and not an alert, that the router has to respect the key's permissions, that every third-party router sees the prompt, that the response model field does not tell you who answered.
What is still missing
The local alias, with a model running on my GPU, does not exist yet. The card is a GTX 1660 Ti, and today it does not work inside a container: nvidia-container-toolkit is missing. Where that engine will run is a decision for later.
And there is an operations lesson I wrote down in big letters: the key that encrypts the credentials in the LiteLLM database cannot be rotated once models are registered. A database backup without that key restores nothing. The two travel together, off the machine.
To build your own
- Spin up a local Kubernetes (k3d, kind or Docker Desktop's).
- Install LiteLLM with Postgres and register two different providers.
- Create capability aliases and set up fallback across providers.
- Give every project a capped key, including your own experiments.
- Break things on purpose: provider down, budget blown, router down. Write down what really happens.
- If you publish anything, publish it behind authentication at the edge, never with an open port.
The rest you learn by breaking it.